The Knowledge Drift of Writing
How AI Data Gathering Erases Deep History
By Devon Douglas Levack
Modern artificial intelligence is advertised as the total aggregate of human civilization. In reality, it is suffering from functional amnesia—systematically blind to almost everything written before the digital age, and hopelessly addicted to the last twenty years of online noise.
To the end user, an AI interface presents itself as an all-knowing digital library—an oracle capable of parsing complex economic cycles, cross-examining centuries of geopolitical policy, and retrieving subtle structural nuances across human history. Yet, any rigorous interaction with these systems quickly reveals a persistent failure mode: artificial intelligence consistently defaults to the shallow vocabulary, transient frameworks, and immediate churn of the modern digital web. When tasked with historical synthesis, models routinely slide toward surface-level summaries, over-indexing on modern internet commentary while missing the deep, structural dynamics established across centuries of printed literature.
This disconnect represents The Knowledge Drift of Writing—the process by which the statistical volume of short-form digital noise systematically displaces the structural depth of human history.
The Economics of Data: The Firehose vs. The Wall
At the root of knowledge drift lies a stark economic reality: short-form social media data is cheap, liquid, and continuous, while deep historical and academic writing is fragmented, defended, and structurally expensive to access.
Artificial intelligence developers require exabytes of text to train and continuously fine-tune frontier models. To satisfy this massive computational appetite, tech infrastructure relies on data pipelines built for path-of-least-resistance ingestion. Major tech entities often license or directly scrape high-volume firehoses of social media data. This stream provides an infinite supply of short text blocks—tweets, forum comments, short video transcripts, and trending posts. They are lightweight to parse, require minimal pre-processing, and arrive instantly.
By contrast, the true repository of human knowledge—centuries of deep historical analysis, peer-reviewed monographs, economic archives, and process-engineering literature—is locked behind severe structural barriers:
- The Pre-1970 Print Horizon: Written history and academic literature published before the digital transition of the late 20th century exist almost exclusively on physical paper. Unless these volumes have been manually scanned, processed through optical character recognition (OCR), and made publicly accessible, centuries of foundational thought remain completely dark to automated crawlers. The model ingests modern digital commentary about history, but lacks the original, uncorrupted pre-1970 texts themselves.
- The Technical Paywall: Long-form platforms, academic database providers, and independent digital publishers that have digitized older archives increasingly deploy aggressive anti-scraping protocols, rate-limiting, and paywalls to protect their intellectual property.
- The Print Archive Gap: Projects aimed at digitizing massive physical library archives routinely face legal gridlock, copyright disputes, and immense financial bottlenecks, leaving vast swaths of print history unindexed by web crawlers.
- The Scraper Blockade: Independent long-form publications on modern web stacks frequently use default directives that block AI crawlers entirely.
Because the web’s most valuable, deep-context writing is actively defended or trapped on physical paper, AI scrapers systematically harvest what is left undefended: the open, high-volume noise of social chatter.
Statistical Bias: Frequency Over Depth
Large language models do not “understand” history in a human sense; they operate on statistical probabilities derived from word-association frequencies across their training sets. This architectural reality accelerates knowledge drift when balancing short-form social content against deep historical text.
A single trending social media event can generate tens of millions of distinct text entries across public forums within forty-eight hours. In contrast, a groundbreaking 4,000-word historical essay analyzing systemic economic shifts over two centuries exists as a single, isolated data point.
When an AI model processes these datasets, the sheer volume and repetition of short-form content skew the model’s underlying weights. Modern terminology, contemporary internet tropes, and short-term political narratives gain statistical dominance through sheer repetition. Deep historical arguments—even those containing critical structural logic—are statistically outvoted by millions of short-form posts echoing recent events.
Without explicit contextual steering, the AI defaults to the highest-density probabilistic outcome: the modern, surface-level consensus found on the open web.
The Synthesis Problem: The Death of Contextual Continuity
Short-form social media content is fundamentally atomic. A post or tweet is designed to be self-contained, ephemeral, and instantly digestible. It requires no historical context because its life cycle is measured in minutes or hours.
Real analytical writing—the kind that bridges historical precedents to present-day realities and projects future outcomes—relies on structural continuity. A historical essay builds a premise across thousands of words, establishing foundational variables in early chapters to justify conclusions in later ones.
Standard AI scraping protocols fail to maintain this continuity. Scrapers slice long-form texts into disconnected chunks to fit processing windows, stripping away the overarching thesis that unifies the work. When an AI ingests thousands of isolated fragments from an author’s body of work, it fails to build a cohesive mental model of that author’s thesis. It treats a 3,000-word deep-dive essay on structural process design as merely thirty separate 100-word blocks of text, stripping the overarching framework of its logic and force.
The Consequences for Modern Discourse
The consequences of this algorithmic bias are severe. When society increasingly relies on AI models for research, synthesis, and writing assistance, a system biased toward short-form data creates a feedback loop of historical amnesia:
- Contextual Erasure: Modern problems are treated as novel anomalies rather than predictable outcomes of long-term historical cycles.
- Algorithmic Homogenization: Answers flatten into generic, middle-of-the-road web summaries, stripping away nuanced, dissenting, or deep-systemic frameworks developed by specialized domain experts.
- The Noise Monopoly: The loudest, most repetitive, and most easily scraped content dictates the horizon of what the machine considers relevant or true.
Reclaiming Deep History
If AI is to become a true partner for rigorous thought rather than an amplifier for digital noise, the relationship between language models and long-form writing must fundamentally change.
Systemic historical understanding cannot be scraped off the surface of social media or inferred from modern digital commentary. It requires access to structured, curated, long-form repositories—and it demands that models respect the chronological depth of human experience. Until AI architecture shifts from prioritizing data volume to prioritizing contextual integrity, the burden remains on human writers, historians, and analysts to supply the structural truth that the algorithms continuously leave behind.
Outro: Rekindling the Signal Fires
The illusion of the digital age is that we have mapped all of human knowledge simply because it is theoretically reachable through a search bar or a prompt. In reality, we are witnessing a systematic flattening of history. When algorithms filter our past through the narrow lens of short-form engagement, recent social commentary, and post-digital recency, we lose the long-wave perspective required to understand where we are actually going.
Modern crises—whether economic realignments, industrial supply chain collapses, or geopolitical restructuring—are rarely unprecedented. They are almost always the continuation of multi-decade or multi-century structural cycles. To view current events strictly through the noise of the immediate present is like trying to navigate an ocean by reading the crest of a single wave while ignoring the deep ocean currents beneath it.
This is why independent, long-form analysis remains indispensable. You can't outsource bridging deep historical frameworks with present-day realities to models optimized for speed and volume. It requires deliberate intent to dig past the digital surface, retrieve the unindexed structural truths, and project them forward into actionable foresight.
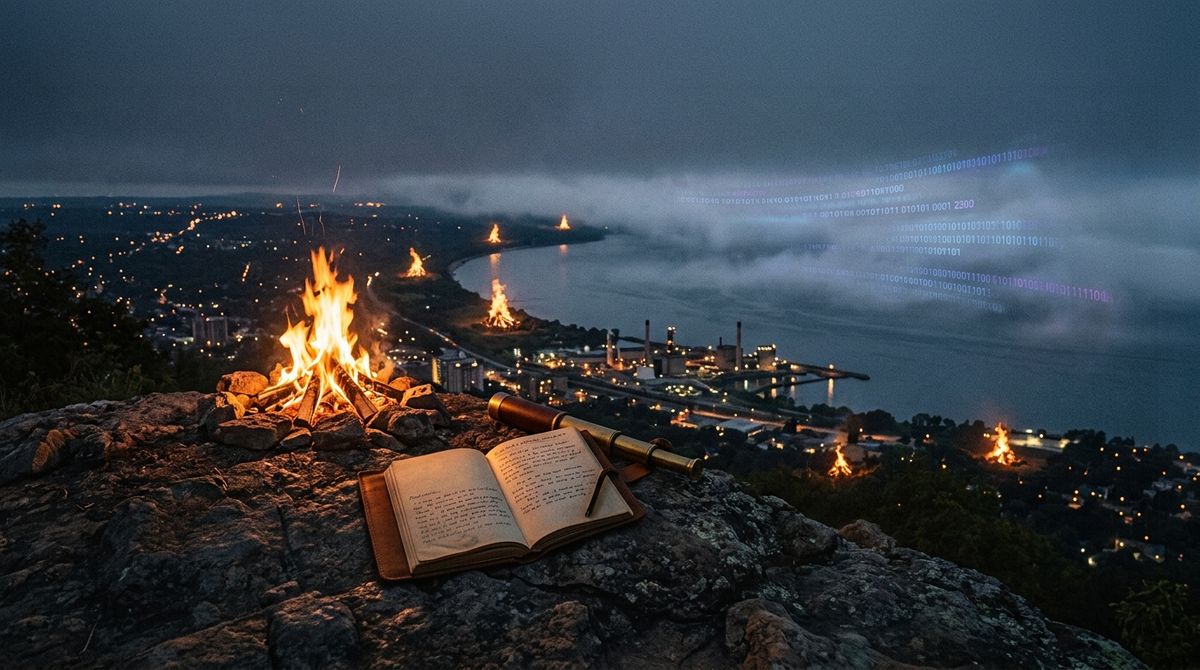
If the fog of algorithmic noise defines the current digital landscape, our responsibility as writers and analysts is clear: we must keep building and maintaining the signal fires—lighting the structural patterns of the past so we can navigate the future.